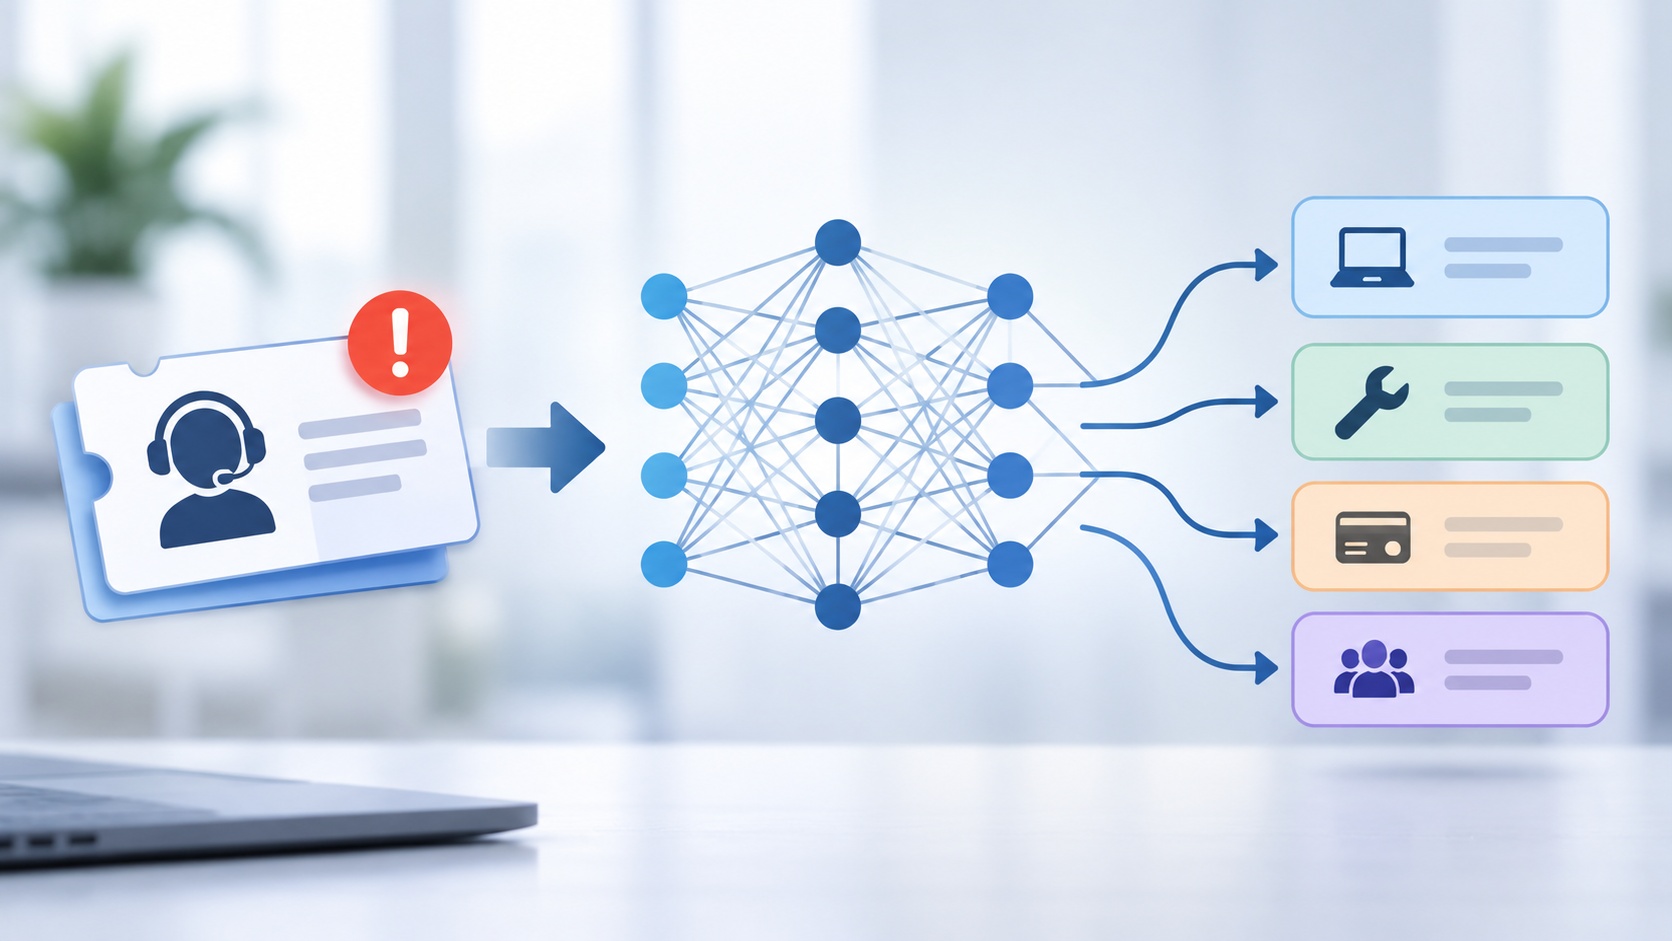
Business Problem
When a ticket reaches the service desk, someone reads its title and decides which team should handle it: application, infrastructure, database or backup. A wrong guess sends the ticket from team to team and delays the fix. Tickets arrive all day, so routing should be automatic, with a person looking only at the tickets the system is unsure about.
Goal
Build a neural network in PyTorch that reads the title of a new incident and predicts which team should handle it (application, infrastructure, database or backup), together with how confident it is.
Dataset
- Training data: incident_tickets.csv
- New tickets to route: new_tickets.csv
- Target column: assignment
Classification Problem
This is a multi-class classification problem: every incident goes to exactly one of four teams. The network gives a probability for each team and the highest one wins. The title is text and a neural network only understands numbers, so you will turn the title into numbers with a pre-trained embedding model before it enters the network.
Technologies and Tools
- Data analysis: Pandas, NumPy, Matplotlib
- Text to numbers: sentence-transformers (all-MiniLM-L6-v2, the embedding model from the embeddings sessions)
- Model: PyTorch (nn.Sequential, nn.Linear, CrossEntropyLoss, Adam)
- Splits and metrics: scikit-learn
- Saving: torch.save, joblib
- Interface (bonus): FastAPI
Tasks
- Explore. Shape, info, and value counts of type and assignment. Look at the length of the titles and read 20 titles of each type. List what you notice, including which rows do not belong in this problem.
- Clean. Keep only what belongs. Drop the columns that cannot help route a ticket including request type. Remove duplicate tickets.
- Features. Turn every title into an embedding, one vector per ticket. Print the number of input neurons your network needs and check that titles with similar meaning get similar vectors.
- Split. Create train, validation and test sets, stratified by assignment, with random_state=42.
- Train. Build the network in PyTorch for the four classes. Start with no hidden layer, then add hidden layers. Plot the training and validation loss for every epoch and choose the number of epochs from the plot. Change one thing at a time and record each result in a table.
- Evaluate. On the test set report accuracy, macro-F1, precision and recall for each team, and the confusion matrix. Read the wrong predictions and decide which ones a human would also find unclear.
- Decide. Use the probability the network gives. Auto-route a ticket only when the top probability is at least X, and send the rest to a person. For several values of X show how many tickets are auto-routed and how accurate those are, then choose X and justify it.
- Inference. Save the model and everything needed to use it again. In a fresh notebook or script, reload it and classify new_tickets.csv into predictions.csv with the predicted team and the confidence. The file contains rows that should not be classified; handle them.
Hints
Try each task on your own first and open a hint only when you are stuck. The hints are questions to think about, not answers.
Tasks 1 and 2: Explore and Clean
- Put 20 Requests and 20 Incidents side by side. How is the wording different? Would you want a model trained on both to route incidents?
- Which columns could a person use at the moment a ticket arrives, and which ones only identify the ticket?
- If the same title appears twice and one copy lands in training and the other in the test set, what does your test score really measure?
Task 3: Features
- A neural network takes only numbers. How did you turn a sentence into numbers in the embeddings sessions, and did you have to train that model?
- Does the length of the vector depend on how long the title is? Print the shape and check.
- Pick one title and find the three most similar titles by cosine similarity. Do they make sense? What does that tell you about the vectors before any network sees them?
- The embedding model stays as it is and only your small network learns. Why is that enough here?
Tasks 4 and 5: Split and Train
- Why must the split happen before anything is learned from the data, such as a scaler or the number of epochs?
- How many outputs does the last layer need? Which loss function suits several classes, and does it expect probabilities or raw scores?
- A network with no hidden layer is the simplest start. Which model from the ML sessions does it behave like?
- If the training loss keeps falling but the validation loss starts rising, what is the network doing? Where would you stop?
- Change one thing at a time: a hidden layer, the number of neurons, the learning rate, the epochs. If you change three at once, what can you conclude?
Task 6: Evaluate
- Backup is the smallest class. Imagine a model that never predicts backup: what would its accuracy be? Which metric would reveal the problem?
- Which two teams does the model confuse most? Open some of the mistakes. Is the model wrong, or is the ticket unclear even to a person?
- Is a bigger network better than a small one here? Repeat each run with a few different seeds and check whether the difference is bigger than the run-to-run noise.
Task 7: Decide
- What does the highest probability tell you about a ticket? Look at a few tickets with a low one.
- A higher threshold makes the routed tickets more accurate but sends more of them to a person. Which costs a service desk more: a misrouted ticket or an extra manual review? Who pays for each?
Task 8: Inference
- Besides the weights, what did you use during training that you need again at prediction time? What happens if the order of the four teams changes?
- What should your code do with a ticket type it should not classify?
Rules
- split before you fit or learn anything from the data
- use only information known when the ticket is created
- set random seeds so results can be reproduced
- AI assistants allowed, but you must be able to explain every line
Notes
Submit: Once the system is ready and tested, share the GitHub link (README, notebook, code, saved model files, predictions.csv) and comment below your test accuracy and macro-F1, and the confidence threshold you chose with the share of tickets it routes automatically.